Background
Continued pretraining (CPT) is widely used to adapt language models to new languages. The technique involves further training pretrained language models (PLMs) on target-language text to improve their language modelling abilities in those languages. CPT is resource-efficient and effective, and is used to develop state-of-the-art models for low-resource languages.
However, the underlying CPT adaptation process remains poorly understood because most studies evaluate CPT-adapted models only after training is complete. To address this gap, we investigate the learning dynamicsHow a model's abilities and internal representations change over the course of training. of encoder-only and encoder-decoder language models during CPT adaptation to South African languages.
Objectives
We aim to better understand the CPT adaptation process by analysing how models change during training.
-
Performance
Analysing downstream task performance throughout CPT helps us understand how models develop language-specific knowledge over time.
-
Internal Representations
Analysing the internal representations of models helps us understand where they represent useful linguistic information.
-
Language Exposure
Comparing models with different levels of prior language exposure helps us understand how existing language knowledge influences CPT adaptation.
Models
We select encoder-only and encoder-decoder models with different levels of prior exposure to our target languages to investigate the role of language exposure in CPT adaptation.
-
English-Only
ModelsOnly pretrained on English, so they have no prior exposure to our target languages.
-
Massively-Multilingual
ModelsPretrained on over a hundred languages, with some prior exposure to our target languages.
-

Nguni-Specialised
ModelsAlready adapted to the Nguni languages, which makes them the strongest starting point for CPT.
Finding: Models with less prior exposure show the largest changes during CPT.
Methodology
-
Continued Pretraining
We adapt the selected PLMs to our target languages through monolingual and bilingual CPT. Throughout training, we save checkpoints of our models for further analysis.
-
Downstream Performance Analysis
We fine-tune each checkpoint on downstream tasks and evaluate its performance using task-specific metrics.
-
Internal Representation Analysis
We analyse how the internal representations of selected checkpoints change during CPT, using cross-lingual geometry analysis and probing.
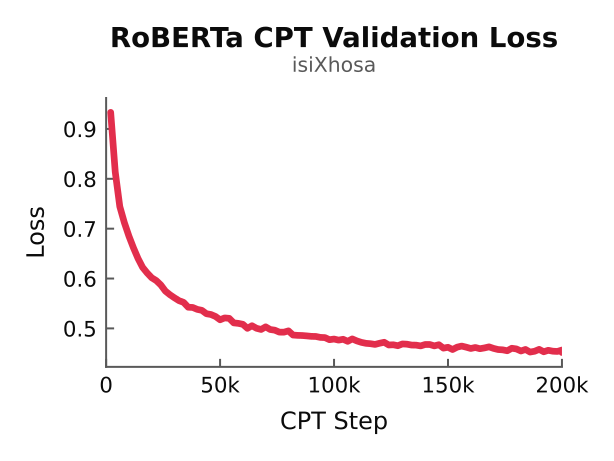
Save checkpoints during continued pretraining
Results
Select a model class to view its results.
Downstream Analysis
We fine-tune each CPT checkpoint on named-entity recognition (NER), part-of-speech (POS) tagging and news topic classification (NTC) in isiXhosa and isiZulu.
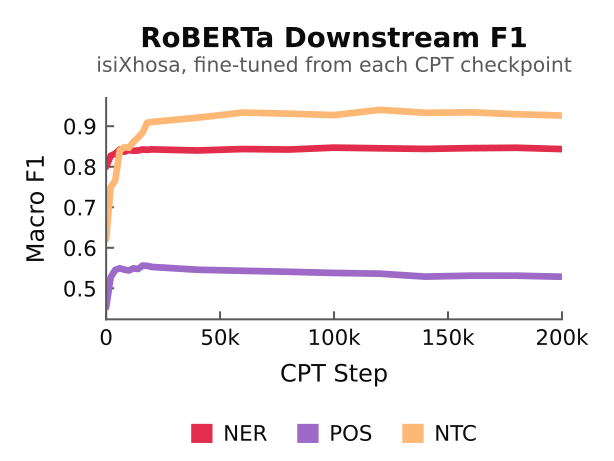
Finding: Most downstream performance improvements happen during early CPT.
Cross-Lingual Geometry Analysis
We then analyse the geometry of the cross-lingual representations of selected checkpoints using IsoScoreHow evenly the model spreads its representations across the available space. and cosine similarityHow closely a sentence lines up with its English translation inside the model..
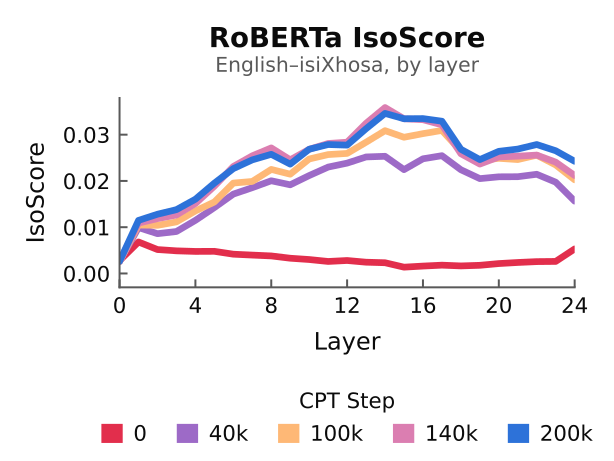
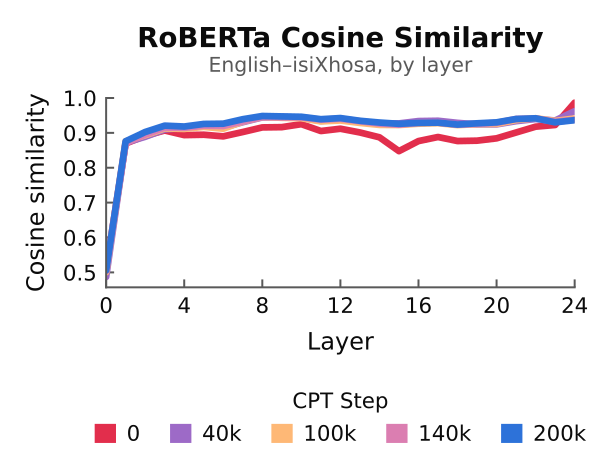
Finding: Monolingual CPT improves alignment, but representational degeneration is present in the final layers.
Downstream Analysis
We fine-tune each CPT checkpoint on machine translation (MT) in both English-to-isiXhosa and isiXhosa-to-English directions, and data-to-text (D2T) generation.
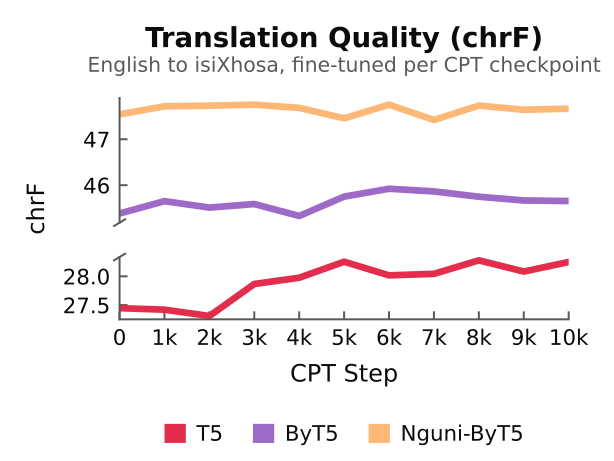
Finding: Encoder-decoder models show limited downstream performance gains during CPT.
Probing Analysis
We then train POS probesSimple classifiers trained on one layer's representations, to test how easily part-of-speech information can be read out. on each layer of selected checkpoints, comparing monolingual and bilingual CPT using accuracy.
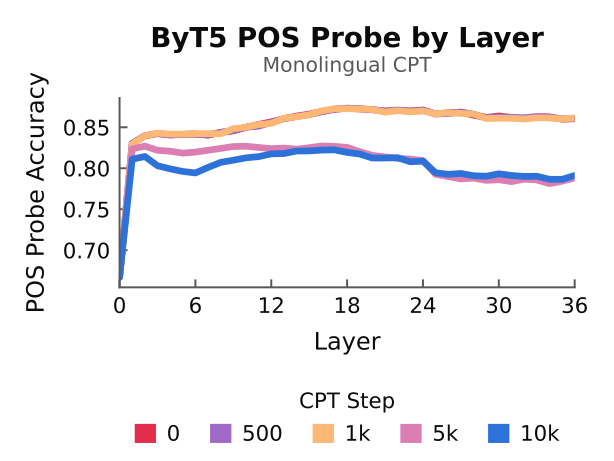
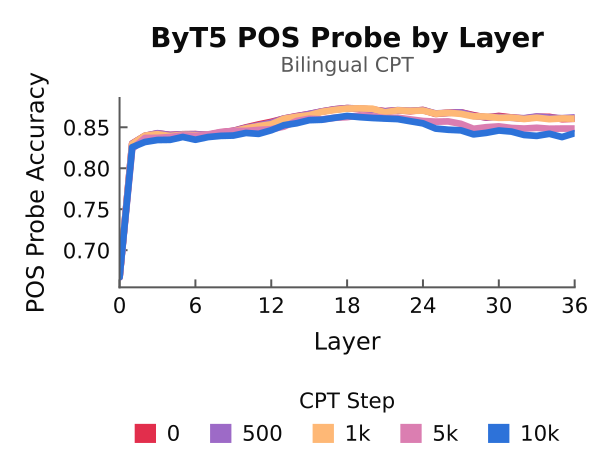
Finding: Bilingual CPT preserves grammatical knowledge better than monolingual CPT.
Conclusions
-
Key Takeaway
CPT adaptation and its benefits depend on model architecture, prior language exposure, and training setup, so all three matter when adapting models to low-resource languages.
-
Our Contribution
We extend learning dynamics research beyond pretraining from scratch, which we hope helps inform more efficient adaptation of PLMs to other African and low-resource languages.
-
Future Work
Future work could explore actionable interpretabilityUsing insights about how a model learns to improve how it is trained. to guide CPT training decisions, and extend our analysis to additional architectures and low-resource languages.
Resources
For more information, please refer to the project documentation below.
-
Siyabonga Madondo
-
Rakeen Ramdeen
-
Overall Project
Project Group
-
Siyabonga Madondo
Author
-
Rakeen Ramdeen
Author
-
Dr Francois Meyer
Supervisor